Why Computer Vision for Manufacturing Pilots Stall Before Full Line Rollout
Jeff Zeller | September 11th, 2026
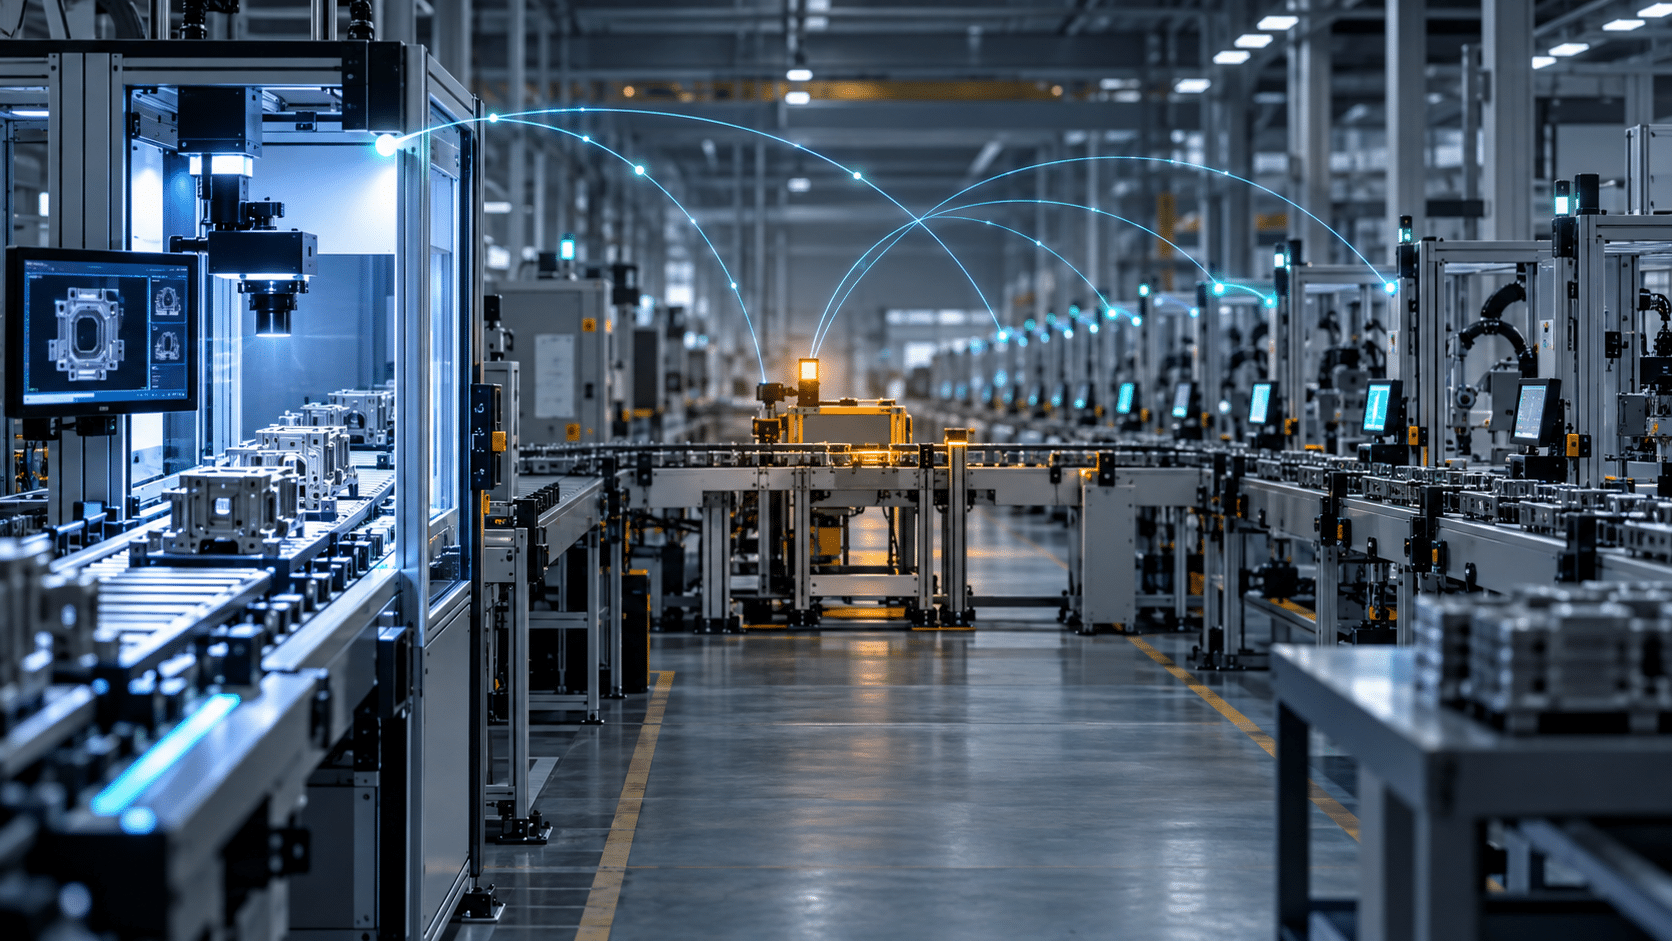
Computer vision usually earns its budget on a single station, and then it has to prove that it can survive an entire plant, which turns out to be a very different technical problem. A detector trained on one camera, one part number, and one lighting condition can post convincing numbers within a few weeks, and that early result is normally what unlocks funding for something wider. The difficulty is that the second station rarely behaves like the first one, and the tenth station may share almost nothing with the original pilot environment. Programs that stall are not usually undone by the model itself, since the detector often continues doing exactly what it was trained to do.
What breaks instead is everything around the model: the capacity to label new defect classes, the resilience of detectors through product changeover, the internal ownership of cameras and data, and the discipline to retrain as conditions move. Those four constraints stay invisible during a proof of concept because a pilot is small enough for one motivated person to hold together by hand.
Where the Pilot Ends and the Scaling Problem Begins
A pilot is built to answer one narrow question, which is whether a model can separate acceptable parts from defective ones under conditions someone controlled on purpose. A rollout asks a much harder set of questions about integration, ownership, and long-term maintenance, and no proof of concept is structured to answer any of them. Teams that have already scaled inspection programs tend to describe the same imbalance, because the majority of the work turns out to be plumbing rather than modeling. Guidance in Computer Vision for Predictive Maintenance: Defect Detection and Inspection AI reports that industrial platforms which deploy successfully spend 80% of the implementation effort on workflow integration and 20% on model configuration, which inverts how most pilots actually allocate attention and staffing. The same source treats the act of connecting fragmented inspection photographs, survey footage, and fixed camera streams into a unified AI classification layer as the single most impactful step managers take, and it points to outcomes such as a 60 percent reduction in manual inspection labor once that layer is in place. A pilot almost never touches that layer, because a pilot runs on one stream that somebody configured manually and monitored personally.
The Four Reasons Computer Vision Pilots Fail to Scale
Four blockers account for most rollouts that quietly stop expanding, and they tend to surface in a predictable sequence as station count grows. Labeling demand compounds faster than the quality team can absorb it, detector performance slips when the line changes over to a different product, ownership of cameras and data falls between quality, IT, and engineering, and no one has built the retraining loop that keeps the original model current. Timeline expectations make each of these harder to absorb, since the same industrial guidance notes that pre-configured vision inspection platforms tend to deploy in roughly 6 to 10 weeks while custom development work runs 6 to 12 months. A program that hits these blockers halfway through a custom build has usually spent its political capital before the second station produces any measurable result.
Labeling Burden Compounds as Defect Classes Multiply
A single-station pilot typically covers two or three defect classes that were chosen because they occur often enough to collect examples quickly. Full line coverage changes the arithmetic completely, because every additional station, product variant, and material supplier introduces failure modes that the original taxonomy never described. Each new class needs labeled examples of the defect itself, and it also needs examples of the near misses that operators currently wave through, which are far harder to gather deliberately. Rare defects create the sharpest version of the problem, since the events that carry the highest scrap or warranty cost are exactly the events with the fewest available images. The labeling work also lands on quality inspectors and process engineers whose time is already committed to production, so the queue grows while the rollout schedule stays fixed. Taxonomy drift makes it worse, because two inspectors labeling the same chip, smear, or misalignment will often disagree about the boundary between cosmetic and rejectable. Matroid users can detect and classify defects, objects, assemblies, hazards, and events, and the custom detector studio with quick training is designed so that adding a class does not require a new development cycle each time. That does not remove the need for careful class definition, and it does not remove the need for technical review of what the detector is actually learning.
Model Performance Drops When the Line Changes Over
Changeover is where most pilots meet their first genuine surprise, because a detector encodes far more of its environment than the people who trained it usually realize. A new fixture, a shifted camera bracket, a different mold, a resin lot with a slightly different sheen, or an afternoon of sunlight through a bay door can all alter the appearance of a part without altering its quality. Operators notice the symptom rather than the cause, so the detector starts flagging good product or missing marginal product, and confidence in the whole program erodes within a single shift. The underlying issue is that the pilot captured one narrow visual baseline and never established a routine for re-establishing that baseline when the line reconfigures. Data retention policy matters more here than most teams expect, and Computer Vision Predictive Maintenance: The Visual Sensor Guide describes a practical split, which is to keep normal-state images only long enough for baseline verification, in the range of 24 to 48 hours, while archiving anomaly images indefinitely for root cause analysis. Applied to changeover, that pattern gives a team a fresh reference set for each configuration alongside a permanent library of every genuine defect the line has produced. Without both halves, every changeover becomes an argument about whether the model or the process moved.
Ownership Gaps Between Quality, IT, and Engineering
The most common reason a successful pilot never becomes a line deployment has nothing to do with vision at all, because it is a question of who owns the system after the pilot team disbands. Quality owns the defect definitions and the disposition of flagged parts, IT owns the network, the storage, the cameras, and the security review that comes with adding streams to the plant network, and controls or manufacturing engineering owns anything that touches line stoppage, alarms, and operator interfaces. A pilot survives without resolving these boundaries because it usually runs on an isolated camera that one champion set up and one champion watched. A rollout cannot, since the same reported 80 to 20 split between workflow integration and model configuration means that the overwhelming majority of remaining work sits precisely in the seams between those three groups. Building the unified classification layer that experienced managers describe as the highest-impact step requires a named owner for camera access, stream reliability, image retention, and alert routing, and none of those responsibilities belongs cleanly to a single function. Budget asymmetry compounds the standoff, because a benefit framed as a 60 percent reduction in manual inspection labor accrues to the quality organization while much of the enabling cost and risk lands on IT and engineering. Programs that scale tend to settle this before the second station is specified, usually by writing down who approves detector changes, who responds to alerts on nights and weekends, and who signs off when a detector influences a hold decision. Vision output should inform those decisions rather than substitute for the trained judgment that compliance and safety functions are accountable for.
No Retraining Pipeline Means the Pilot Model Runs Forever
The quietest failure mode is a detector that keeps running long after the conditions it learned have changed, and nobody notices because nobody is measuring it. A pilot ends with a model artifact, not with a pipeline, so there is usually no mechanism for capturing the misses that operators correct at the station and feeding them back into training. Over months, the gap between what the model was trained on and what the line actually produces widens, and the practical result is either alert fatigue from false flags or silent misses that show up later as customer complaints. Sustaining performance requires a governed loop, which starts with the retention pattern described in Computer Vision Predictive Maintenance: The Visual Sensor Guide, where short-lived normal-state images support baseline verification and archived anomaly images support root cause analysis. It also requires that someone review flagged and corrected cases on a set cadence rather than only after an escape. The financial case depends on that loop existing, because the return models people build during a pilot assume sustained performance rather than a one-time result. The same guide illustrates how quickly visual monitoring can pay back, describing labor reductions in the range of 80 to 90 percent for route-based tasks such as reading gauges or checking oil levels, and a payback period under four months on labor savings alone for a system costing around 15,000 dollars. Those numbers only hold if the detector remains accurate against current production, which is exactly what a frozen pilot model cannot promise.
What a Scalable Computer Vision Deployment Architecture Looks Like
A deployment built for a line rather than a station looks structurally different from a pilot, and the difference is mostly about layers rather than models. The point of the architecture is that adding a station becomes a configuration exercise instead of a new project, which is what allows a program to move at the 6 to 10 week pace reported for pre-configured inspection platforms rather than the 6 to 12 month pace of custom development, with four elements carrying most of that weight.
- A capture layer that accepts existing plant hardware, so cameras, video streams, and stored inspection imagery all feed the same system without a hardware replacement program.
- A unified classification layer that consolidates fragmented image and video sources, described in industrial deployment guidance as the highest-impact step managers take.
- An integration layer that routes results into the workflows people already use, including operator alerts, hold decisions, and quality records, since that is where the reported 80 percent of implementation effort belongs.
- A retraining loop with explicit data retention rules, a review cadence, and named owners for detector changes and alert response.
The strategic reason to invest in that structure is that visual monitoring pushes work from reactive to planned, and Computer Vision Predictive Maintenance: The Visual Sensor Guide frames the benchmark plainly: According to ReliabilityWeb, best-in-class organizations spend less than 10% of their maintenance effort on reactive work. Inspection follows the same logic, because catching a defect at the station that created it costs far less than discovering a pattern after a shipment.
How No-Code Detector Platforms Address the Specific Blockers
No-code platforms matter here for a narrow and practical reason, which is that they move detector creation to the people who already understand the defect. Matroid is an enterprise no-code computer vision platform for creating, deploying, and managing visual AI detectors, and its custom detector studio with quick training is built so that a new defect class can be defined, trained, and evaluated without a bespoke engineering project each time. That directly addresses the labeling bottleneck, because the quality specialist who can distinguish a rejectable chip from a cosmetic one no longer waits in a development queue to encode that distinction. Matroid software works with any image or video hardware, which addresses the capture problem that stops many rollouts before they begin, since existing plant cameras and stored footage can feed the same detectors rather than requiring a fresh hardware standard per station. Users can detect and classify defects, objects, assemblies, hazards, and events, so one platform can cover inspection at the station, assembly verification downstream, and process monitoring elsewhere in the facility. The platform also includes MLOps architecture and analytics from video streams, which is what makes the retraining loop and the performance review cadence something a team can actually operate rather than something an individual maintains informally. None of this removes the need for technical oversight, and it should not be read as a substitute for engineering review, validation against current production, or the professional judgment that quality, safety, and compliance teams are accountable for. What it changes is where the effort goes, because when detector creation stops consuming the schedule, the integration and ownership work that determines whether a rollout succeeds finally gets the attention it needs.
The Decision Before the Next Station Goes Live
The most useful moment to confront these blockers is before the second station is specified, since that is when a program still has the credibility from its pilot and has not yet accumulated technical debt across a line. Four commitments make the difference, and each one is an organizational decision rather than a modeling decision. Someone in quality has to own defect class definitions and the labeling capacity required to keep expanding them as products and suppliers change. Someone has to own the changeover protocol, including how a fresh visual baseline gets established when fixtures, materials, or lighting move. IT and engineering have to agree on camera access, stream reliability, image retention, and alert routing, because the reported 80 percent of implementation effort that goes to workflow integration lives entirely in that territory. Finally, the program needs a retraining cadence with a named reviewer, so that the detector running in month eighteen reflects the line as it exists rather than the line as it was during the pilot.
Teams that settle those four questions early tend to find that the rest of the rollout moves at the pace associated with pre-configured platforms rather than multi-quarter custom builds, and the labor benefits described in industrial deployment guidance become durable instead of one-off. Teams that skip them usually end up with a very good demonstration at one station and a stack of unopened proposals for the rest of the plant. If you are weighing where computer vision fits across your line, a scoped demo against your own footage and defect classes is the fastest way to test whether the architecture holds. Get a demo from Matroid to see how no-code detectors, camera-agnostic deployment, and video stream analytics apply to the stations you plan to bring online next.
TL;DR: Manufacturing computer vision programs stall not because the model fails but because the surrounding infrastructure, including labeling capacity, changeover resilience, data ownership, and retraining discipline, cannot scale beyond the single motivated person who held the pilot together.
Building Custom Computer Vision Models with Matroid
Dive into the world of personalized computer vision models with Matroid's comprehensive guide – click to download today